Downloadable kit
Freshness Guard
Kit files are in English.
Make your agent search before it states a fact that may have changed, and measure how often your models skip it.
Python 3.9+. Hooks and skill for Claude Code, rule blocks for any agent, bench for OpenAI-compatible and Anthropic APIs.
- Flag time-sensitive prompts with rules you can read, and add a search-first note before the model answers.
- Send an unsearched answer back once, with an optional Stop hook that cannot loop.
- Measure how often your own models skip the search, with the harness from the post and 40 sourced questions.
Local Python kit | ZIP, guide and reports in English | Offline demo
$29One-time payment
I'm a subscriber: check my accessYearly: every kit included. Monthly: one new kit per billing cycle.
Delivered downloads are non-refundable. Return policy
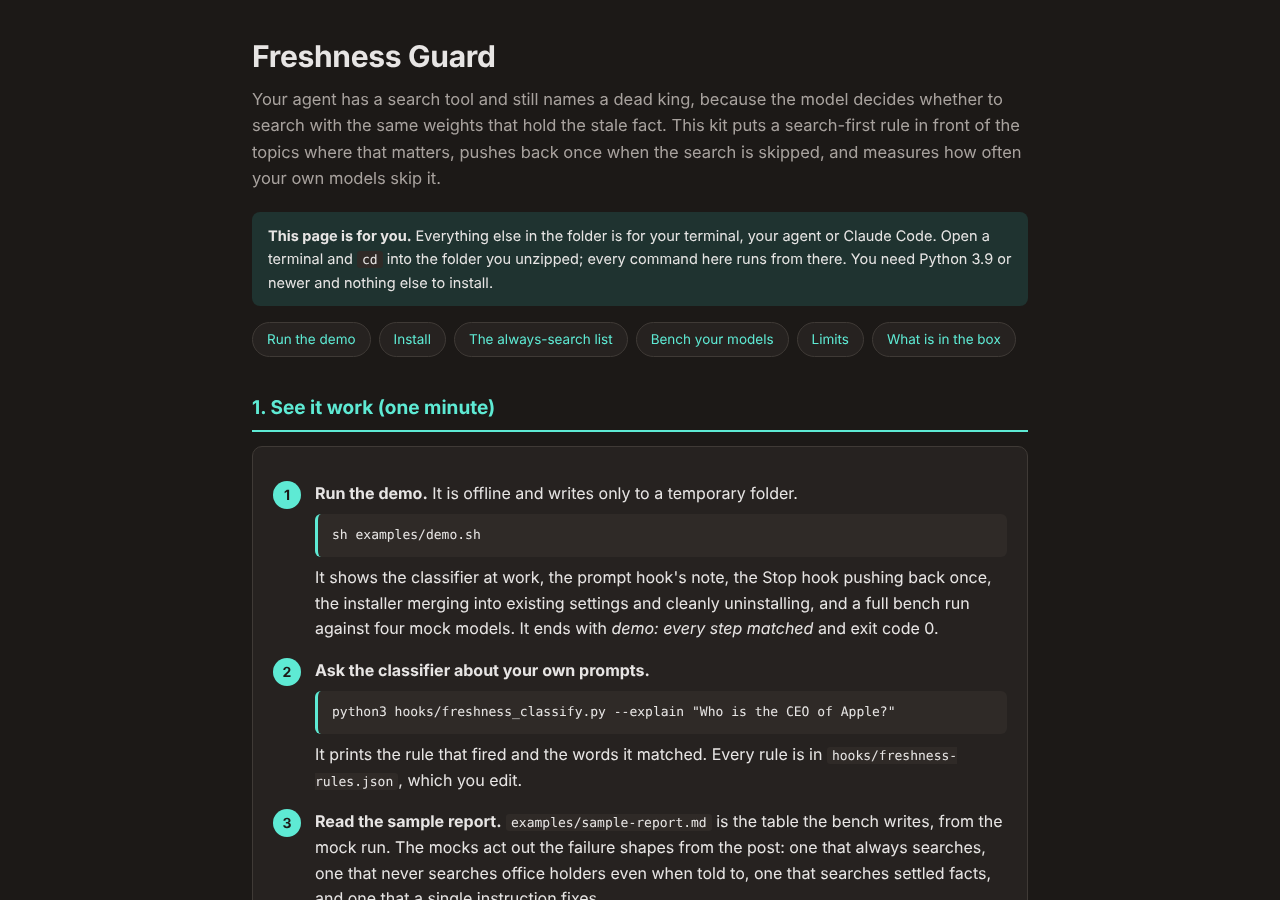 View full-size sample ↗
Access, downloads and refund policy
Yearly: every available kit and bundle, unlimited downloads.
Monthly: one new standalone kit per billing cycle, no bundles. Re-downloads are free and do not use a new claim.
Monthly subscriptions started before February 28, 2026 keep all-access, including bundles and unlimited downloads.
Monthly access currently allows three downloads per kit. Need another? Contact joozio@hey.com.
Download access while subscribed. Keep the files you download.
Digital downloads are non-refundable once delivered. We resend broken links, replace corrupt files and review products significantly different from their description case by case. Contact joozio@hey.com with your order details. Return policy
How it works
King Harald V of Norway died on 28 August. A few weeks later I gave 16 AI models a web search tool and asked who the king is. Five of them named Harald. One of those had a system prompt telling it to search first. The tool was there every time. The model decides whether to use it, with the same weights that hold the old fact, so it skips the check exactly where it feels most sure. My own agent has a rule about this with one word in capitals, because it kept getting model names and prices wrong. This kit is that rule, set up for your agent. A Claude Code skill and two rule blocks list what always needs a search: AI models, prices, software versions, people's roles, office holders, news, sports, laws and rates, anything dated. A prompt hook adds a search-first note when a prompt matches rules you can read and edit in one JSON file. An optional Stop hook sends an unsearched answer back once and cannot loop. The installer merges into your settings and backs them up first. The benchmark from the post runs on your own models with 40 questions, each with its source, the 20 time-sensitive ones checked on 30 October. Standard library Python, and the demo runs offline.
From the Digital Thoughts experiment that gave 16 models a search button. 113 tests on Python 3.9 to 3.14 as of October 30, 2026
Latest update: 2026-10-30
v1.0.0 (2026-10-30). First release.
Best for
- +Anyone whose agent has web search and still states model names, prices or versions from memory
- +Claude Code users who want the check in a hook, not only in a rule the model can skip
- +People choosing a model for an agent who want to measure how often it skips the search before trusting it with current facts
Not for
- -Forcing a model to search. The note and the rule raise the odds; the post showed a model that ignored an explicit instruction. The Stop hook pushes back once and then lets the agent stop
- -Grading answers. The bench records the decision to search; it does not run the search or judge what the model said, and its stale check is a marker match listed per answer so you can read it
- -Hooks in other agents. The hooks are for Claude Code; other agents get the rule blocks and the bench
What you get
Package includes
- •START-HERE.html: run the demo, install, the always-search list, bench your models, limits
- •hooks/: prompt_guard.py, stop_guard.py, freshness_classify.py, freshness-rules.json, and settings-snippet.json for a manual install
- •bin/install.py: project or user install, dry run, Stop hook on or off, uninstall
- •claude/skills/freshness-check/SKILL.md
- •snippets/: CLAUDE.md-rule.md and AGENTS.md-rule.md
- •bench/: run.py, providers.py, scoring.py, 40 questions (20 time-sensitive and 20 evergreen controls, each with its source), a models file to copy and four offline mock models
- •examples/: demo.sh, seven sample transcripts for the Stop hook, and sample-report.md
- •guide/: three chapters on tuning the rules, running the bench and refreshing the questions
- •tests/: 113 tests across the classifier, the hooks, the installer, the bench and the providers
- •README.md, SETUP.md, MANIFEST.txt, CHANGELOG.md, LICENSE.txt
FAQ
Will my agent search every time now?
No. The prompt hook puts a search-first note in front of the model when a prompt matches a rule, and the model still decides. The optional Stop hook catches a flagged question answered with no search or fetch call and sends it back once. The classifier is keyword and pattern rules, not judgment: on the 40 bench questions it flags all 20 time-sensitive ones and one evergreen one. On your prompts it will miss some and flag some it should not, and --explain shows you which rule fired so you can edit it.
Can the Stop hook get stuck in a loop?
No. It allows the stop whenever stop_hook_active is true, records each prompt it blocked so it never blocks the same one twice, and allows the stop on any error. It reads the Claude Code transcript file, whose line format is not a documented interface: lines it does not understand are skipped, and when it cannot find the prompt it allows the stop. Claude Code writes the transcript asynchronously, so the worst case is one unnecessary push back.
Does anything leave my machine?
The hooks, the installer, the demo and the tests never touch the network. There is no account and no telemetry. The bench calls only the endpoints you put in your models file, with keys read from environment variables you name.
Which models can the bench test?
Any OpenAI-compatible chat completions endpoint (OpenAI, OpenRouter, a local server) and the Anthropic Messages API. With the defaults, one model with a cutoff set is 320 calls: 40 questions, 4 system prompts, with and without the tool. No live provider was called while building the kit; both adapters are tested against recorded request and response shapes, and SETUP.md says what to change if a provider rejects a parameter.
What do I have to install?
Python 3.9 or newer, standard library only, and Claude Code for the hooks. All tests and the demo pass on Linux under Python 3.9 to 3.14 and on macOS on Apple silicon under Python 3.9 and 3.14, where both hooks also ran in a real Claude Code session. No Windows run has been recorded; SETUP.md covers the parts that are platform specific.
The questions are dated. What happens when they go stale?
Every time-sensitive question was checked on 2026-10-30 against the source listed with it, and the harness warns once a question is older than --max-age-days (60 by default). The third guide chapter shows how to refresh them and write your own.
How do I switch it off?
Set FRESHNESS_GUARD_OFF=1 in the environment Claude Code runs in, or put a skip phrase such as "from memory" in a prompt. To remove it, run the installer with --uninstall: it takes out only what Freshness Guard added and backs the settings file up first.